Resaro accredited under the AI Verify Foundation’s AI Tester Accreditation Programme (AI TAP) Read more

AI Testing and Continuous Validation

Evals engineers trust.
Go/no-go decisions leaders can defend.

Continuous testing and validation that moves AI from lab performance to operational deployment. Tested against real world conditions, across modalities, giving ML engineers quality gates in CI/CD and structured evidence leadership can act on.

Scenario-specific. Traceable. Configurable.

ResaroDashboards
Trusted by
f3bce637a24862c365144c7098ae341f1511435b
a73ab93ba235e9c3a4a4ebd8fbb5b48799e0d437
ca1e039c2905f06212312a9cb967ae2850a1f8bc
4dad09434b4a210278cea2fd85d92d0d3f637dff
Logo (2)
Logo (3)
Logo (4)
f3bce637a24862c365144c7098ae341f1511435b
a73ab93ba235e9c3a4a4ebd8fbb5b48799e0d437
ca1e039c2905f06212312a9cb967ae2850a1f8bc
4dad09434b4a210278cea2fd85d92d0d3f637dff
Logo (2)
Logo (3)
Logo (4)
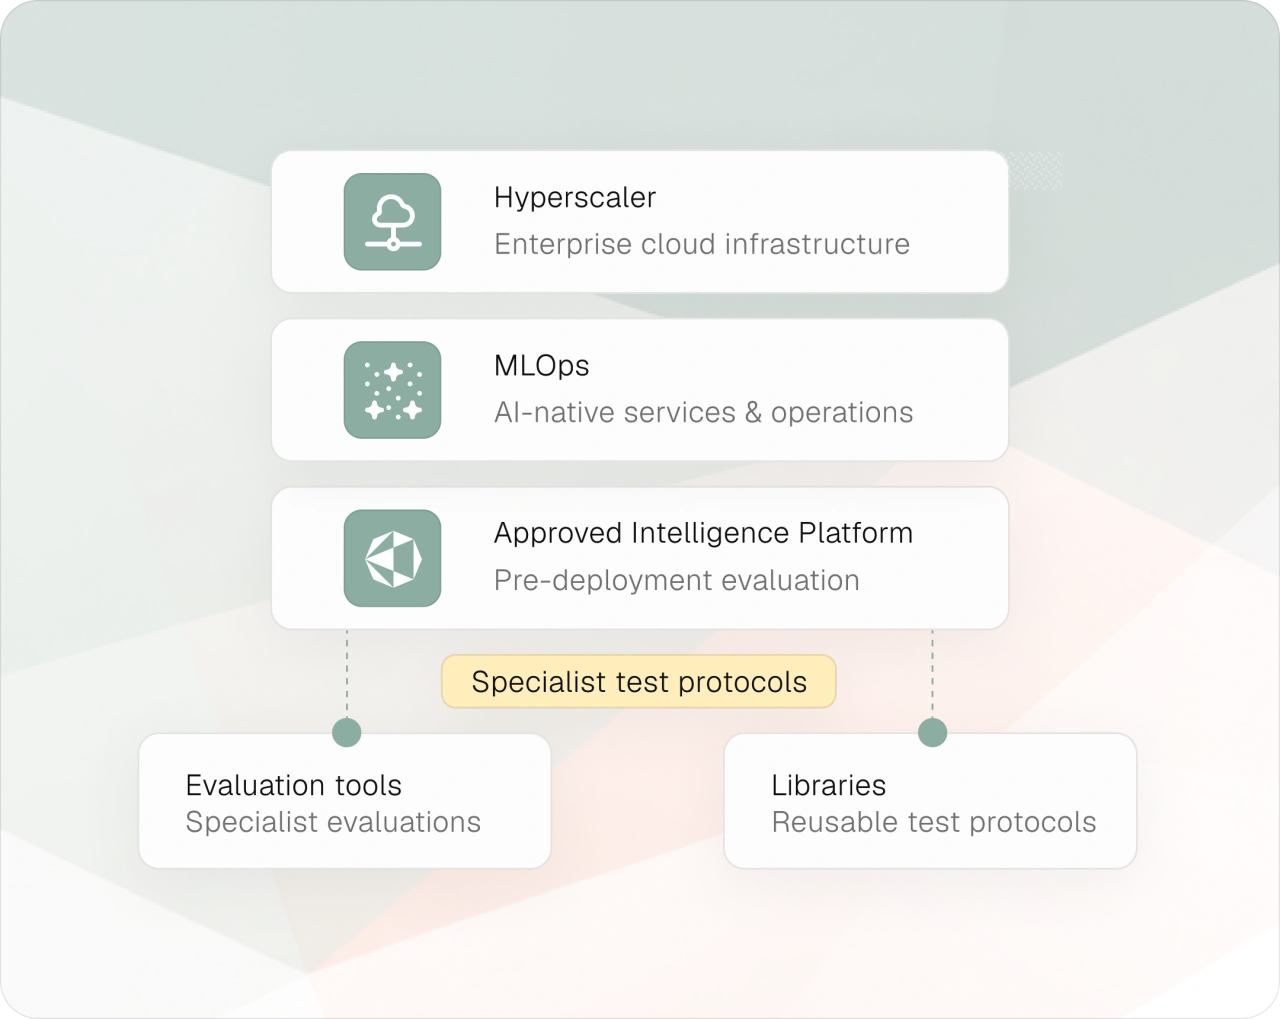
AIP: approved intelligence platform

Catch failures before they’re silent. Test against the conditions you haven't seen yet.

The risk isn’t what your evaluation catches, but what it never tested. Known failure modes are easier to test for. The challenge is uncovering what you’ve overlooked.

CD
ON-PREM AND AIR-GAPPED

In-environment testing. No data leaves your perimeter.

Build it once.
Reuse again and again.

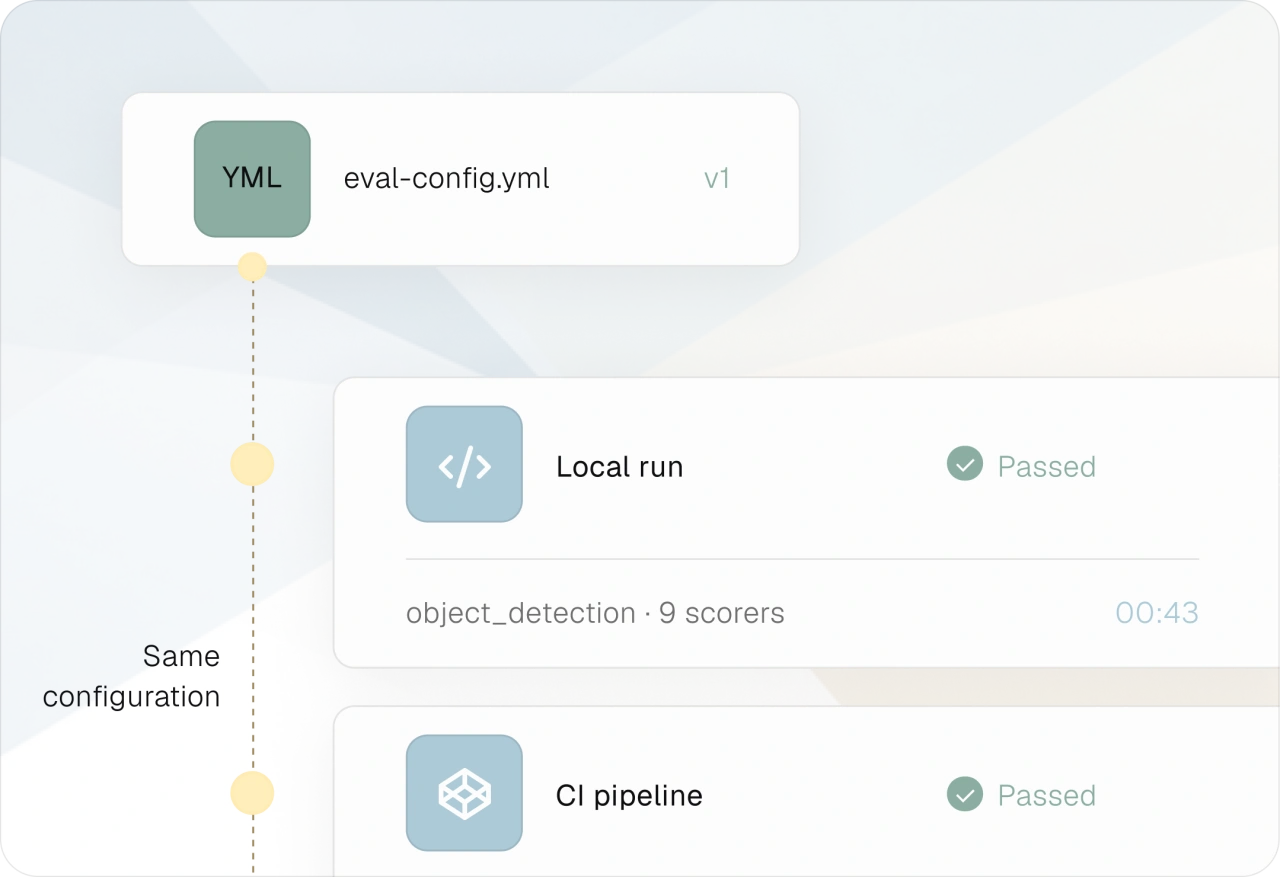
Use the Python SDK to define your evaluation workflow. Register and version datasets, metrics and configs once, then reuse them across runs and teams instead of rebuilding them for every model.
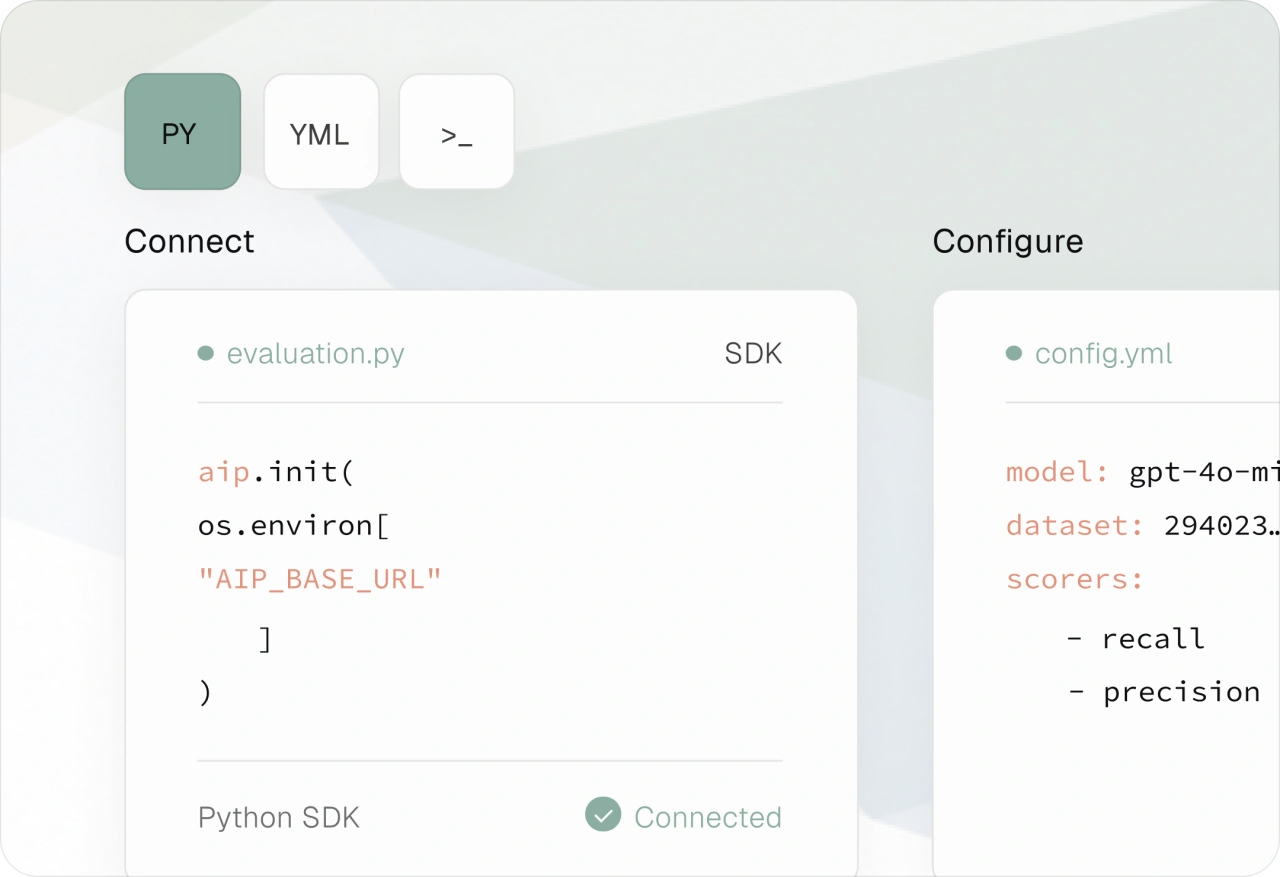
SDK and config as code (6)

Evals built into your pipeline, regressions caught early.

Run the same evaluation suite on your laptop and as a step in CI. Every pull request gets a clear pass or fail, so regressions are caught while the code is still open.
CD

Speed up dataset prep, keep the rigour.

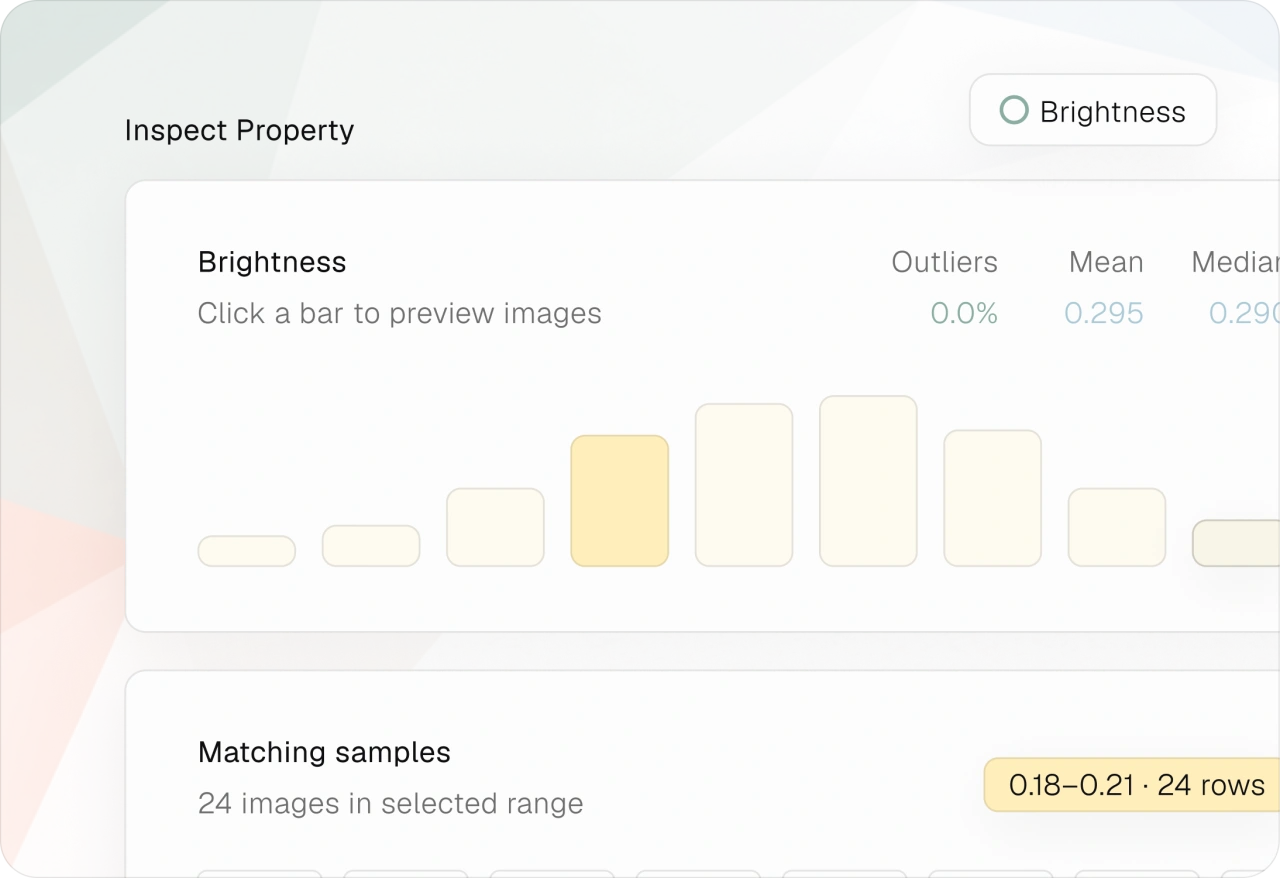
Bring data in the formats you already use. AIP converts it to a versioned evaluation format and checks it for duplicates, broken files and coverage gaps before a single test runs.
Dataset prep built in (1)

Cover the edge cases before your users do.

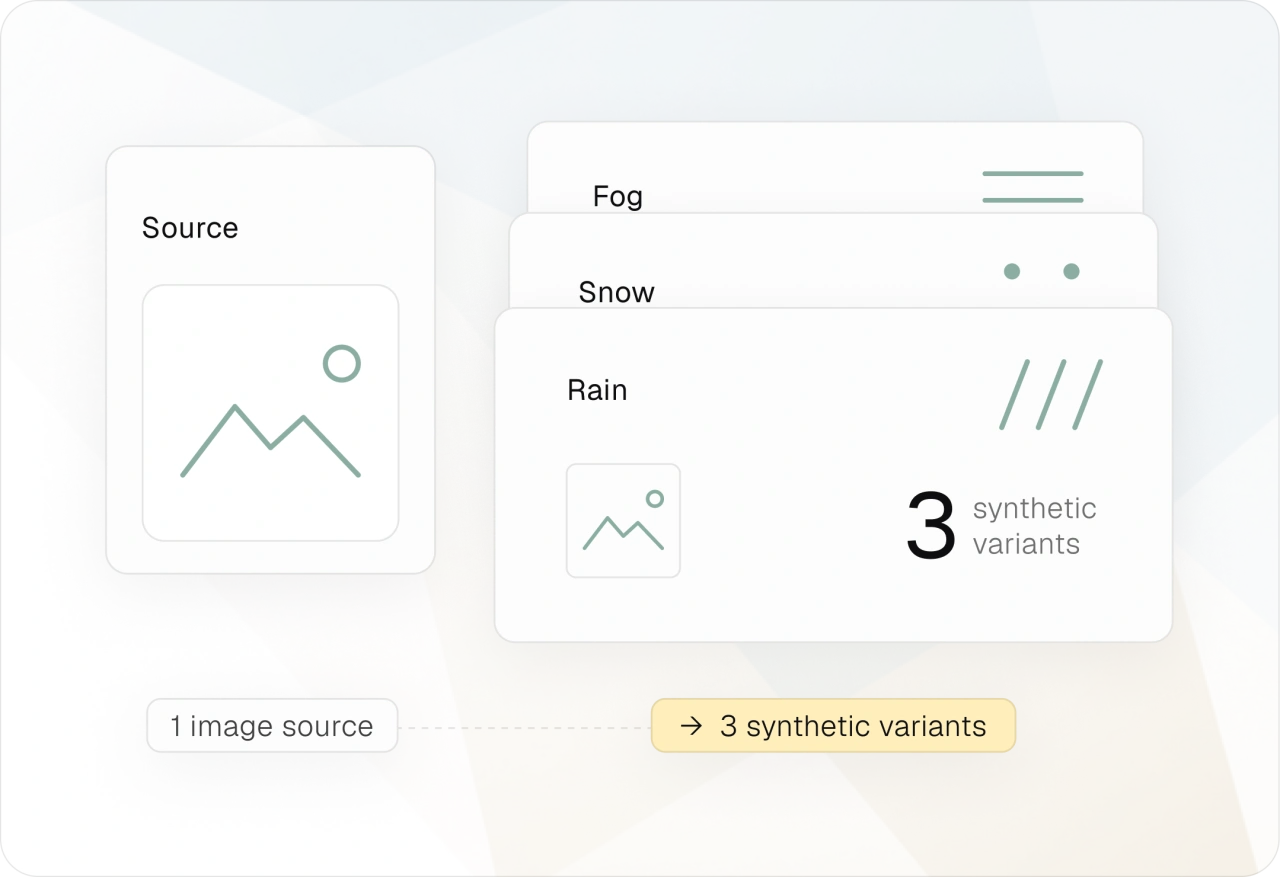
Synthetic data fills the conditions your test set is missing, like fog, rain, snow and low light. One source image becomes several variants, so you test the failure surface, not just the average case.
Synthetic Data Generation (1)

Secure, enterprise ready deployment options.

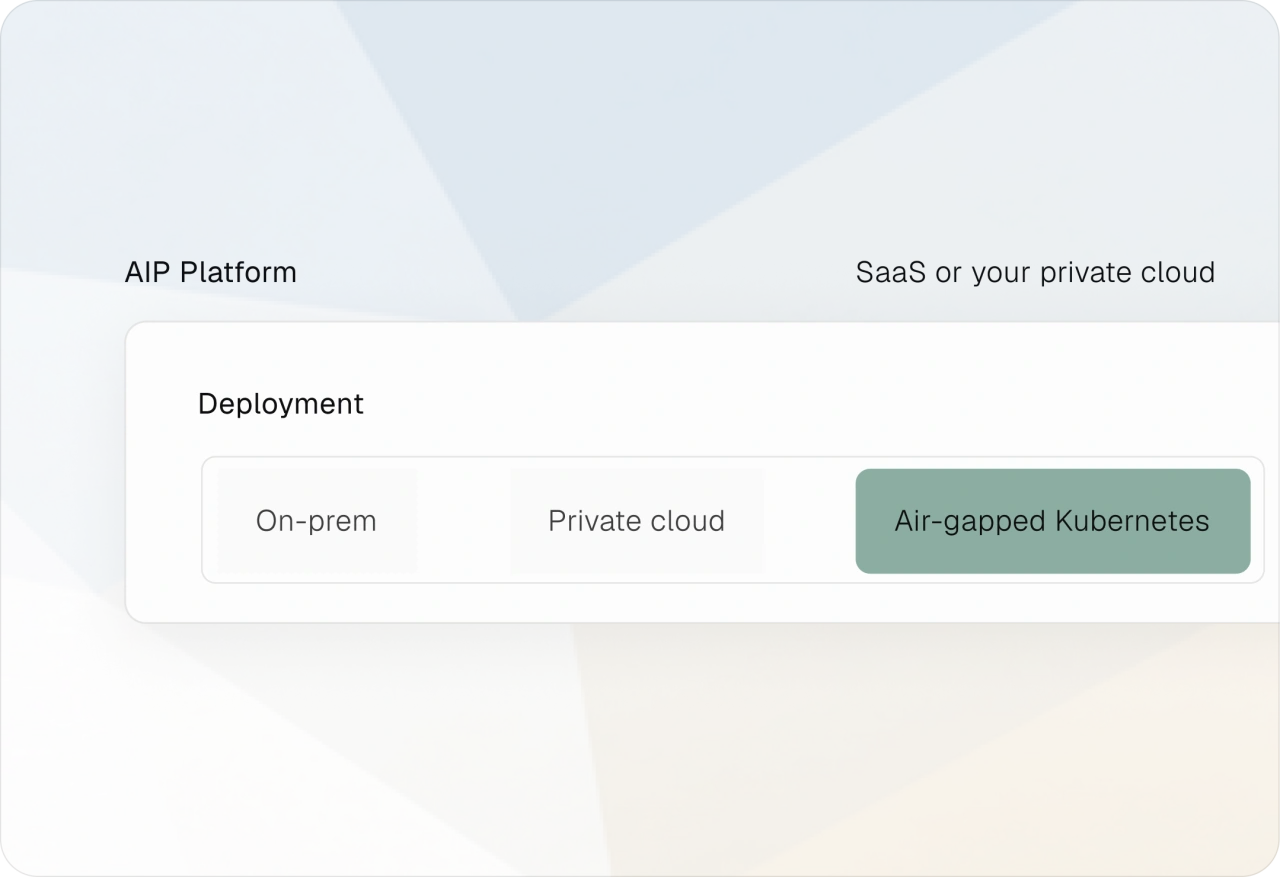
Deploy on-prem, in your private cloud, in your own Kubernetes cluster or fully air-gapped. No telemetry or external calls required, so your data never leaves your environment.
or air gapped Kubernetes

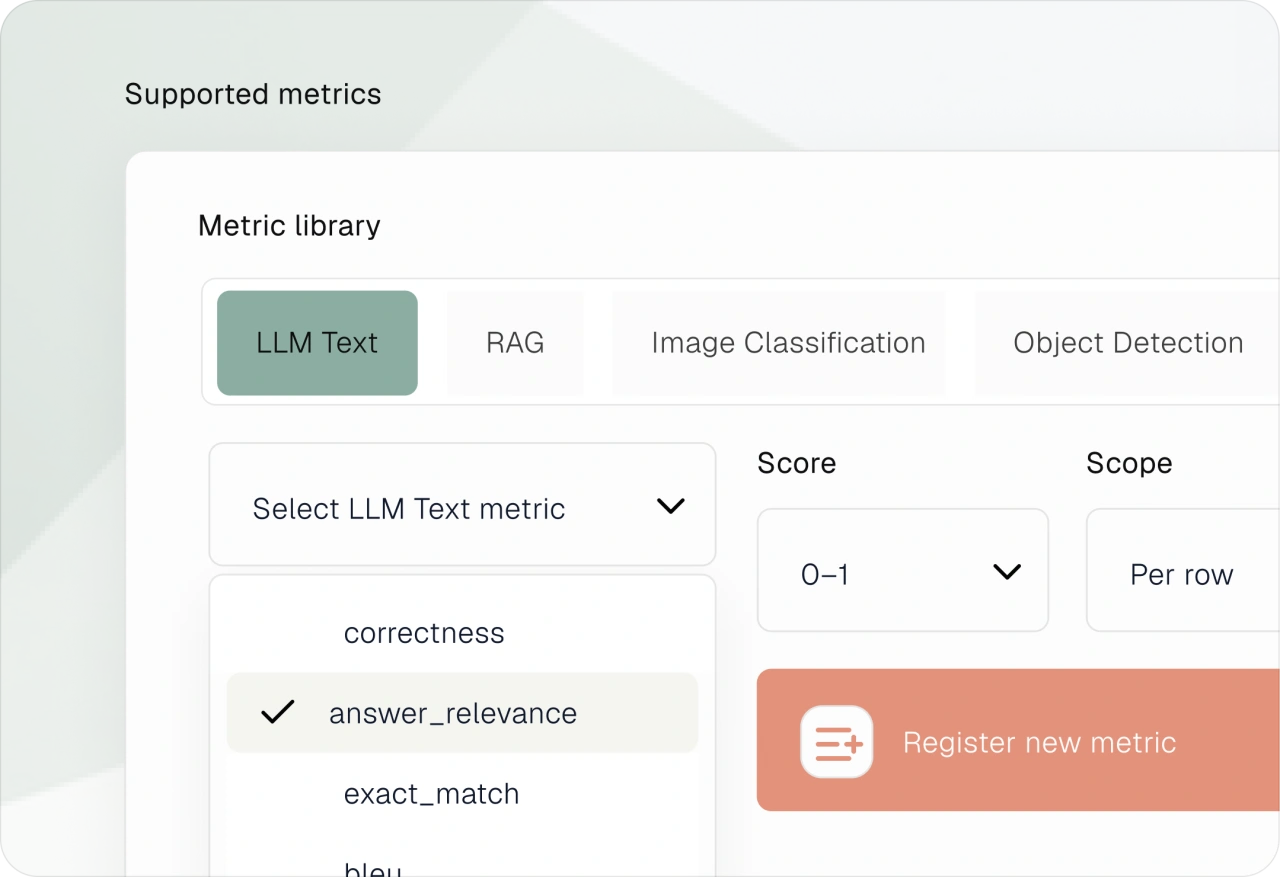
Use our metrics. Or bring your own.

Start from a metric library organised by modality, from LLM and RAG to object detection. Set your own thresholds, or register your own scorer and it runs in the same pipeline as ours.
Metric library with configurable parameters (1)
MULTI-MODAL AI TESTING AND CONTINUOUS VALIDATION

What it evaluates

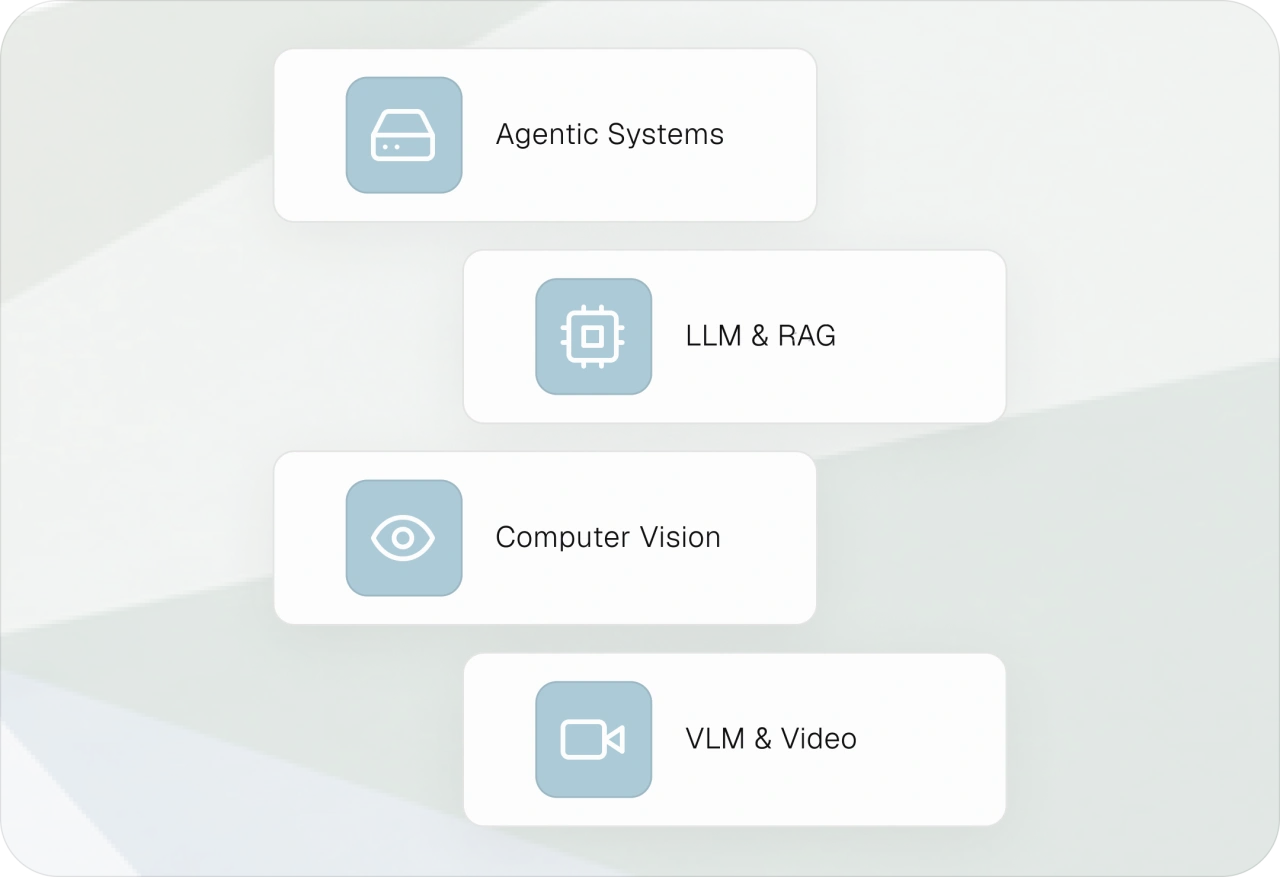
The AIP evaluates agentic workflows, multimodal systems and safety-critical models where trajectory testing and synthetic edge cases are the difference between a benchmark and operational proof.

SDK and config as code (7)
REPORTING FOR ENGINEERS AND LEADERS

Clear results for engineers. Clear answers for leaders.

Frame 1000000959

ML Engineer

A shared evaluation standard and CI/CD-native gates. 
Every new model is a new evaluation cycle, not a new 
one-off project.

user check

Decision-maker

A defensible go/no-go artefact from the same engineering run. Traceable, comparable, and defensible to a board, regulator, or end user.

FOR THE ML ENGINEER

Every run reports itself, from pass/fail down to the data behind each failure.

Define evaluations the way you define infrastructure - versioned, reviewable, identical locally and in CI/CD. No UI dependency. No separate reporting step.

code package code (2)

Dataset prep that is evaluation-aware

Bring Your Own Data augmented with synthetic data generation for the edge cases you don't have coverage for. 

flag off

Pick the metrics. Set the thresholds

Pick the metrics. Set the thresholds. Built-in scorers for each modality, plus your own custom metrics in the same pipeline.

settings 2

Failure analysis and continuous improvement

One evaluation config runs in your local environment and in CI. Clear pass/fail signals. No rebuilding per context, no surprises at the gate.

shield alert

Enforce quality gates in CI/CD

Block regressions before they reach production. Evaluation runs automatically at every merge, not as a manual step after the fact.

Define evaluations the way you define infrastructure - versioned, reviewable, identical locally and in CI/CD. No UI dependency. No separate reporting step.

code package code (2)

Dataset prep that is evaluation-aware

Bring Your Own Data augmented with synthetic data generation for the edge cases you don't have coverage for. 

flag off

Pick the metrics. Set the thresholds

Pick the metrics. Set the thresholds. Built-in scorers for each modality, plus your own custom metrics in the same pipeline.

settings 2

Failure analysis and continuous improvement

One evaluation config runs in your local environment and in CI. Clear pass/fail signals. No rebuilding per context, no surprises at the gate.

shield alert

Enforce quality gates in CI/CD

Block regressions before they reach production. Evaluation runs automatically at every merge, not as a manual step after the fact.

FOR THE DEPLOYMENT DECISION MAKER

Get AI to production faster, with every go/no-go defensible evidence.

Reporting your board can read. A traceable pass/fail for every system, linked to the data, test and threshold behind it.

terminal browser (1)

Comparable across time and vendors

Re-run the same evaluation spot drift, or put competing systems through the same test.

file warning

No separate write up

The evidence comes from the same run your engineers already execute.

Reporting your board can read. A traceable pass/fail for every system, linked to the data, test and threshold behind it.

terminal browser (1)

Comparable across time and vendors

Re-run the same evaluation spot drift, or put competing systems through the same test.

file warning

No separate write up

The evidence comes from the same run your engineers already execute.

GET STARTED

Keep your next project out of the AI pilot graveyard.

Book a technical briefing with our engineering team.